Optimizing cost and latency with Amazon Bedrock prompt caching
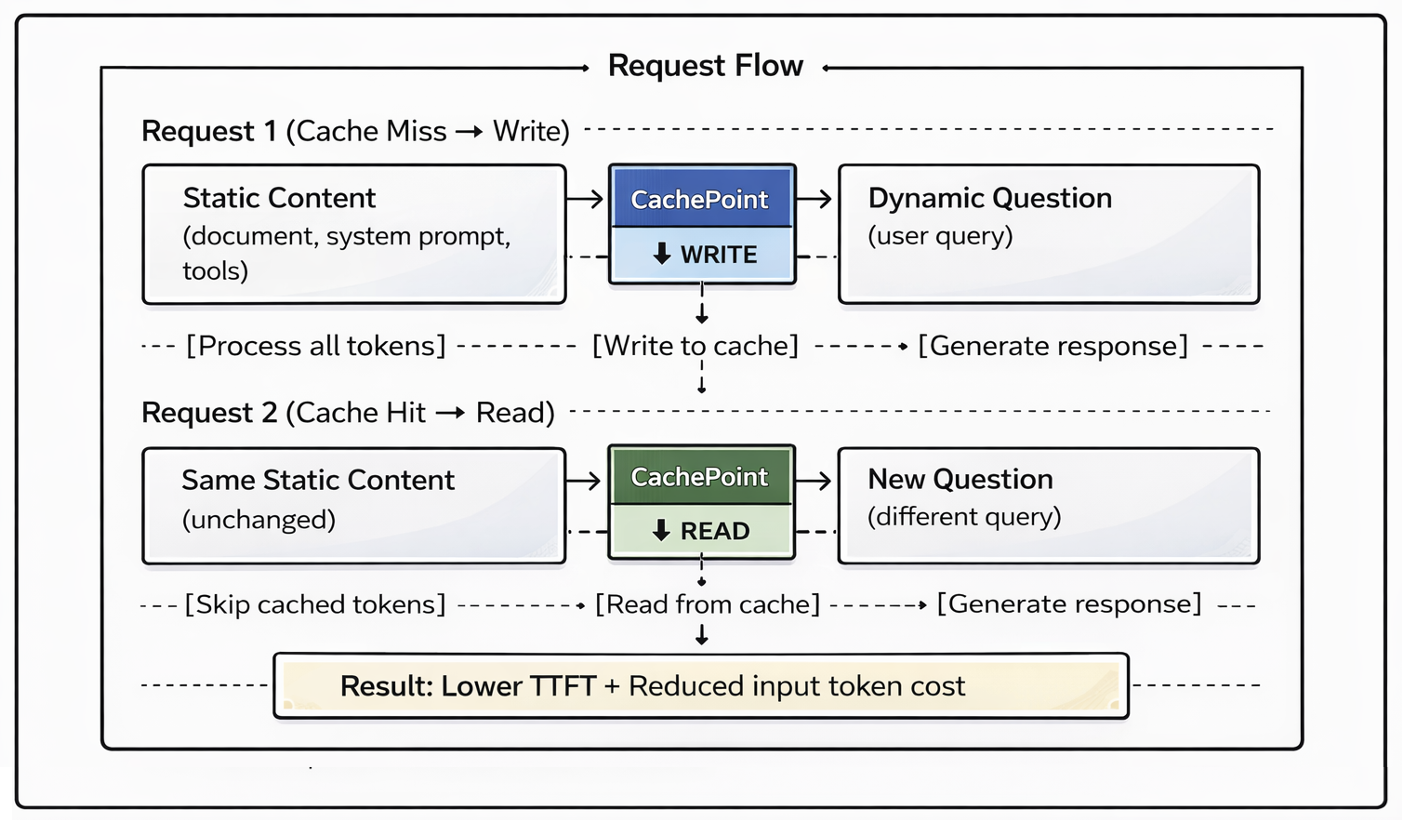
Prompt caching in Amazon Bedrock can reduce your input token costs by up to 90 percent when you repeatedly send the same context to foundation models, based on Amazon Bedrock prompt caching pricing. Without caching, a 10,000-token contract sent alongside 50 user questions means 500,000 input tokens billed at full price for content the model […]
Optimizing cost and latency with Amazon Bedrock prompt caching Read More »