AI agents now run in production at a scale of billions of operations a day, and a recurring architectural pattern has surfaced: agents need a compute scratch pad. Not only for coding tasks, but for data aggregation, analysis, verification, and any workflow where semantic reasoning alone isn’t enough.
Abnormal AI, a behavioral security service that protects more than 25 percent of the Fortune 500, has deployed Amazon Bedrock AgentCore Code Interpreter, a capability of Amazon Bedrock AgentCore. Abnormal AI uses it for the agents that support its real-time inline email threat detection. These systems run in production today, processing billions of messages and executing agent-driven code at that same scale to detect and block threats inline, before they reach the inbox.
This work is part of how Abnormal AI builds software. Today, 80 percent of their code changes are built using an agent in some way, and 40 percent are built end-to-end by a background agent (fully AI built, not AI assisted). Their use of AgentCore Code Interpreter for threat detection reflects the same AI-native approach applied to their production runtime.
In this post, we share how Abnormal AI architected these systems, the design decisions behind their sandbox approach, and practical lessons for builders deploying Code Interpreter at scale.
What is Amazon Bedrock AgentCore Code Interpreter?
Amazon Bedrock AgentCore Code Interpreter provides a fully managed, serverless runtime for agents to execute code dynamically. Key characteristics include:
- Ephemeral MicroVM sessions: configurable time-to-live from 15 minutes (default) up to 8 hours for long-running tasks.
- Security: sessions run in secure sandboxes with full separation at the host operating system level, designed to help prevent inadvertent disclosure between sessions.
- Flexible networking: configurable for sandbox virtual private cloud (VPC) mode, or public internet access.
- File handling: up to 100 MB through the API directly, or connect to Amazon Simple Storage Service (Amazon S3) for larger datasets.
- Preloaded runtimes: Python and
Node.jsenvironments with common visualization, statistics, and data processing libraries. - Built-in observability: logs sent to Amazon CloudWatch and AWS CloudTrail for monitoring.
Critically, Code Interpreter is exposed as an API. This means it doesn’t dictate the agent’s workflow. Instead, it provides a box where the agent can run commands, upload files, and retrieve results. For teams with existing agent infrastructure, this plug-and-play design makes the integration straightforward.
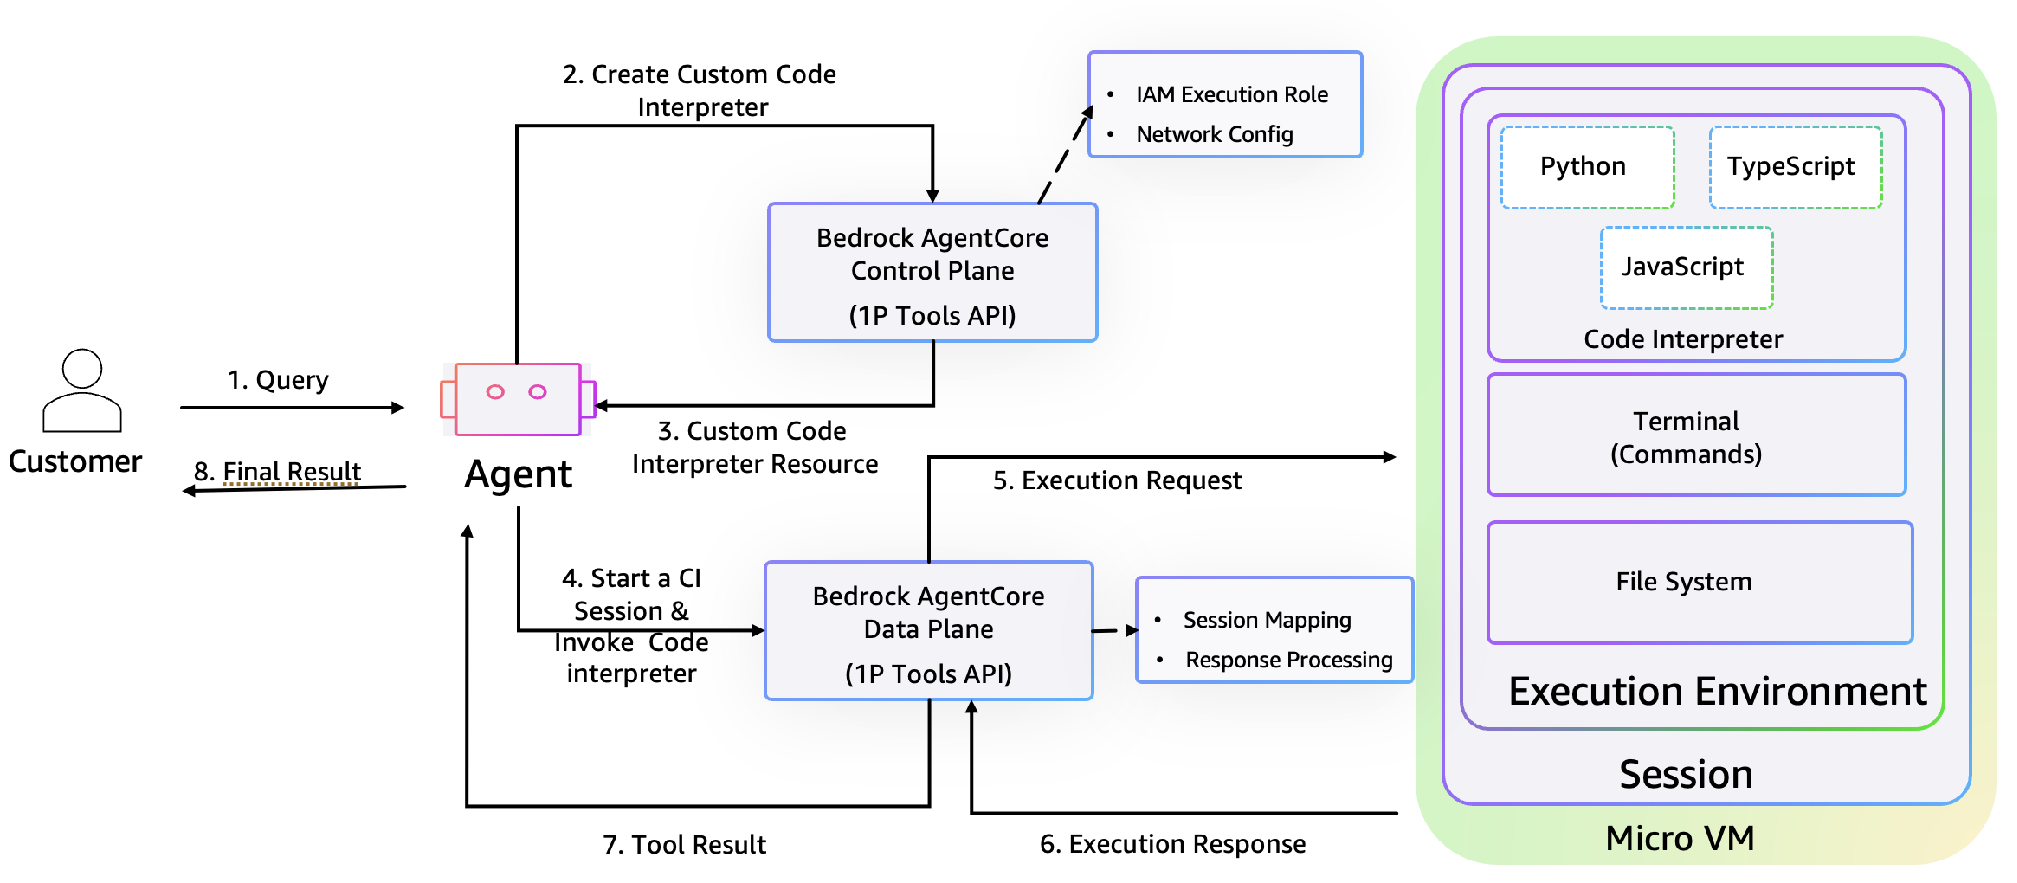
Figure 1: Amazon Bedrock AgentCore Code Interpreter architecture, where the agent invokes the Code Interpreter API to provision an ephemeral MicroVM sandbox session for code execution, file input and output, and result retrieval
Why agents need a compute scratch pad
Large language models (LLMs) excel at reasoning and semantic coherence, but many real-world operations don’t map to semantic reasoning:
- Basic math and counting: “How many phishing email did we detect in the past hour?” requires computation, not language generation.
- Data processing and visualization: transforming raw data into charts, PDFs, or structured reports.
- Code verification: running unit tests, linting, and integration tests to validate agent-generated outputs.
By pairing a large language model with Code Interpreter, you enhance the agent’s capabilities beyond what reasoning alone can achieve.
“Pretty much any agent, whether it’s writing code or not, needs a code interpreter sandbox that allows it to actually crunch data and come to answers.”
— Shrivu Shankar, VP of AI Strategy, Abnormal AI
Abnormal AI’s architecture: Three-tiered detection at billion-message scale
Abnormal AI processes billions of email messages through a three-tiered detection architecture, as shown in Figure 2.
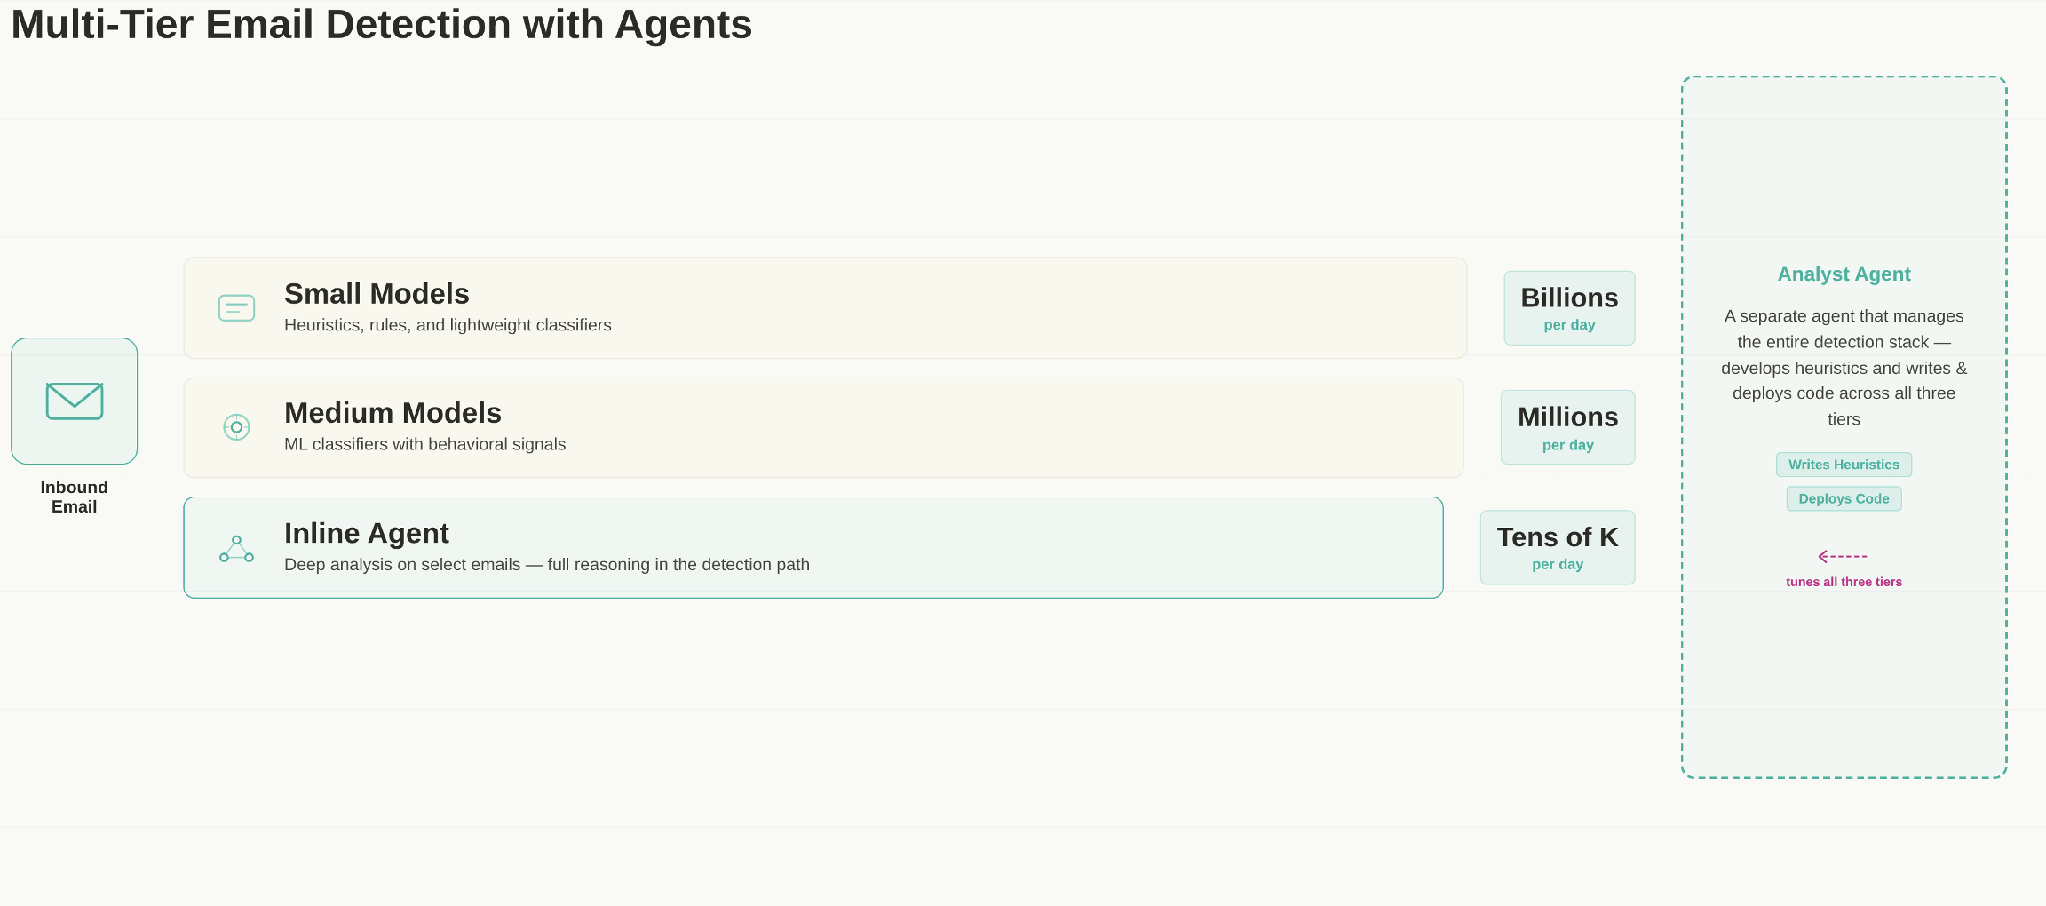
Figure 2: Abnormal AI’s three-tiered email detection pipeline, with Tier 1 (heuristics, billions/day), Tier 2 (machine learning models, millions/day), and Tier 3 (inline agents with Code Interpreter, tens of thousands/day), where each tier handles progressively harder cases that the previous tier was unconfident about
Tier 1 — high-volume lightweight classification (billions/day)
Small models, heuristic rules, and lightweight classifiers (logistic regressions) handle the largest volume of traffic. At this scale, it’s both cost-prohibitive to run larger models and unnecessary. Most messages can be classified without deep analysis.
Tier 2 — medium models for uncertain cases (millions/day)
Messages that Tier 1 is unconfident about flow into deep learning and machine learning (ML) models that perform more behavioral signal analysis.
Tier 3 — inline agents with Code Interpreter (tens of thousands/day)
The hardest cases, which would typically require a human analyst to evaluate, are processed by inline agents. These agents receive the threat intelligence data and use a sandbox to analyze it, writing scripts dynamically. They then evaluate how it fits into the overall behavioral model and make a determination. Misclassifications are handled by a separate system that learns and improves the system. A variety of monitoring systems verify the live system.
The analyst agent — batch intelligence
Beyond the real-time classification pipeline shown in Figure 2, Abnormal deploys an analyst agent that operates in batch mode (Figure 3):
- Ingests misclassifications and tuning signals from its detection pipeline.
- Identifies patterns and trends across large message sets.
- Autonomously writes draft candidate heuristics for Tier 1, operating on Abnormal AI’s own detection-pipeline features and signals.
- Improved models for Tier 2.
- Runs on the scale of approximately 100 batch jobs per week.
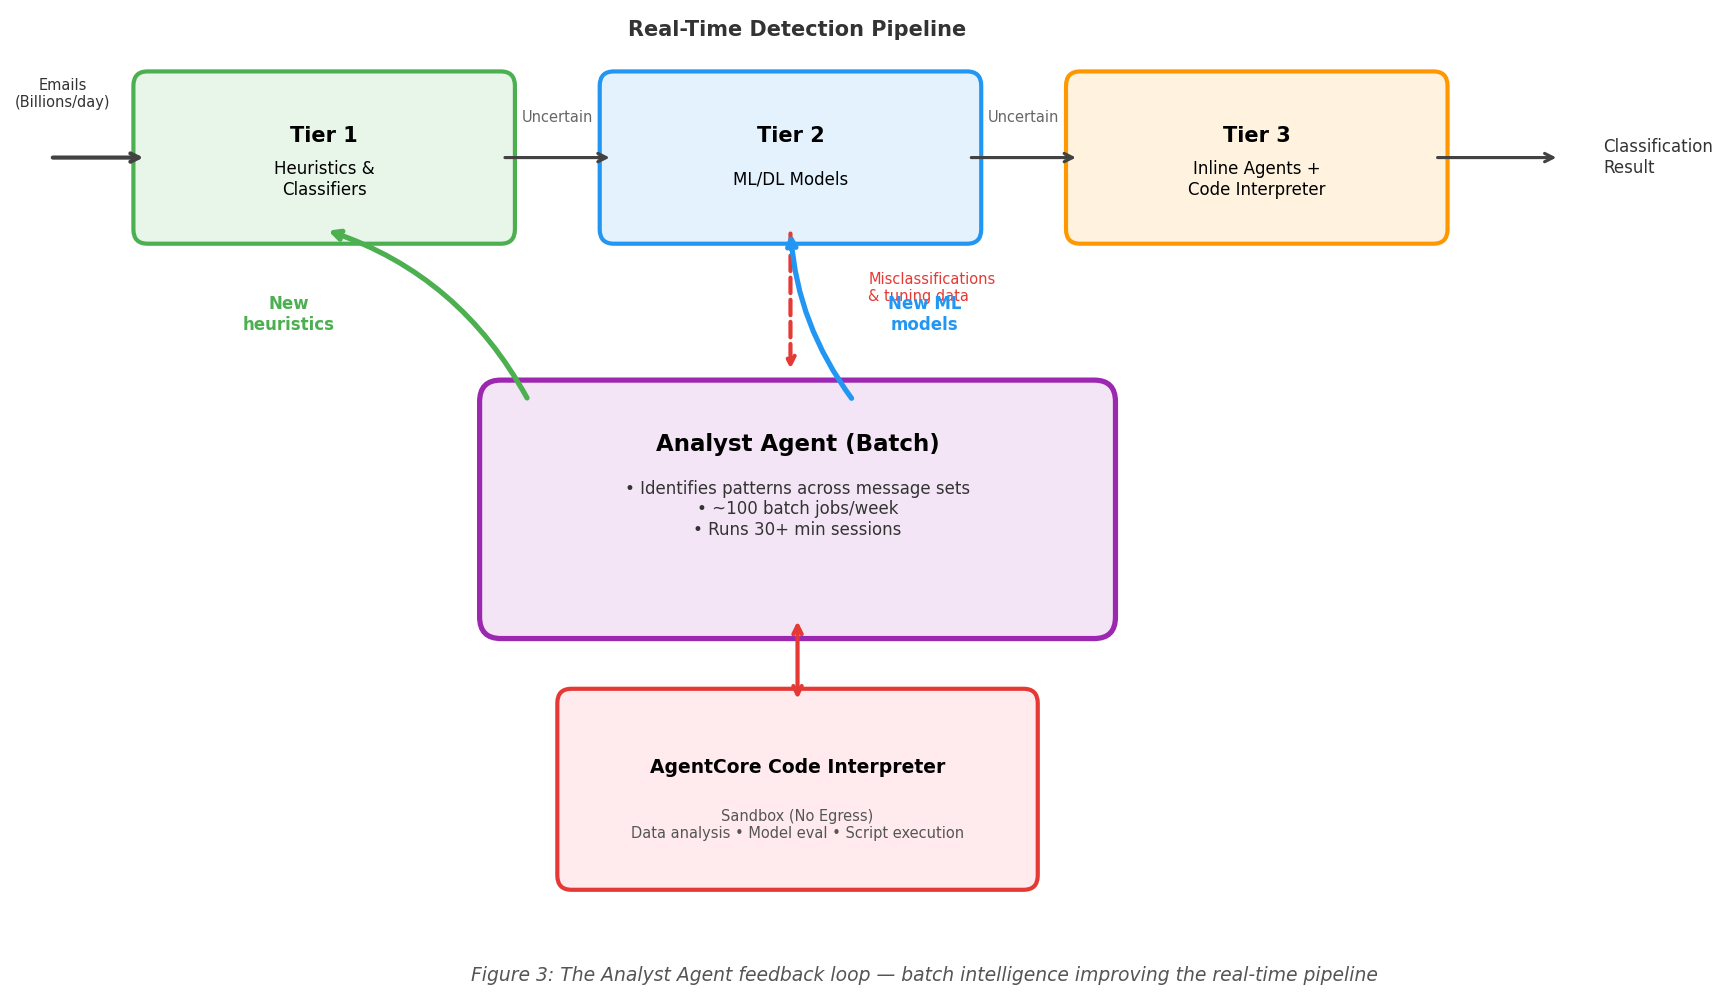
Figure 3: The analyst agent feedback loop, where the batch agent ingests misclassifications from the real-time pipeline, analyzes patterns using Code Interpreter sessions, and feeds improved heuristics and models back into Tier 1 and Tier 2
These batch jobs can run for more than 30 minutes with Code Interpreter sessions maintained throughout. They can also span day-long operations where the agent uses Code Interpreter intermittently. For example, it runs a session, trains a model externally, then re-invokes Code Interpreter to process the result.
Security: Zero-trust sandbox design
Abnormal chose the sandbox (no egress) configuration for Code Interpreter driven by two considerations:
- Reproducibility – Because the sandbox has no external network access, nothing outside Abnormal AI’s control can influence the agent’s behavior during that session. The environment is designed to be fully deterministic.
- Data exfiltration prevention – threat intelligence data enters the sandbox for analysis. Even if the agent becomes malicious through prompt injection or stochastic behavior, it is designed to prevent the exfiltration of that data to the internet.
Additional security practices:
- Controlled data ingestion: intentional about what types of data enter Code Interpreter and what write actions are permitted.
- Subprocessor alignment: Code Interpreter operates under the existing AWS subprocessor relationship and reduces compliance overhead.
- Network isolation layering: sandbox isolation on top of their existing network-isolated harness provides defense in depth.
Lessons learned and best practices
Several practices emerged from running Code Interpreter in production at Abnormal AI.
1. Give the agent what it wants
Agents perform better with a lightweight, general harness rather than rigid step-by-step workflows. Provide high-level principles for solving a problem and let the agent use its intelligence to determine the approach.
2. Every agent needs a scratch pad
Code Interpreter isn’t only for coding agents. Security agents analyzing email benefit from compute scratch pads for data aggregation, pattern analysis, and verification.
3. Use programmatic verifiers as guardrails
Agents deliver higher quality outputs when they have programmatic verification tools. Unit tests, integration tests, and linting allow the agent to self-test within the sandbox before delivering final results.
4. Use file systems as recovery points for long-running tasks
For operations exceeding the Code Interpreter session time (for example, model training), use the file system as a checkpoint. Run Code Interpreter for computation, persist state to files, perform long-running operations externally, then re-invoke Code Interpreter to process results. The analyst agent (Figure 3) uses this pattern for day-long model training operations.
Conclusion
Abnormal AI’s implementation demonstrates a key insight for production agent systems: Code Interpreter is not merely a coding tool. It’s fundamental infrastructure that agents use to reason computationally. By combining the managed, secure sandbox of AgentCore Code Interpreter with their own lightweight agent harness, Abnormal achieves:
- Zero-trust security posture through sandbox isolation helping prevent data exfiltration.
- Billion-message scale by reserving agent compute for the hardest cases (Figure 2).
Whether you’re building security agents or a system where agents need to crunch data and verify their own outputs, the pattern is clear. Give your agents a scratch pad and trust their evaluations more than you trust their assertions.
Next steps
- Get started with Amazon Bedrock AgentCore Code Interpreter.
- Explore AgentCore capabilities and other tools (Gateway, Memory, Runtime, Identity).
- Learn more about Abnormal AI at abnormalsecurity.com.
Abnormal AI is an AWS customer. The views and opinions expressed in this post are those of the customer and don’t necessarily reflect the views of Amazon Web Services.
About the authors