Blog_dumb

Deepgram deepens Amazon SageMaker AI observability with Enhanced Metrics

Deepgram deepens Amazon SageMaker AI observability with Enhanced Metrics

Self-hosted speech AI has historically carried an observability trade-off. The service can tell you an endpoint is up and how many requests it served. The questions that actually drive capacity planning and cost management stay locked inside the vendor’s container: what you are billed for, which features your traffic uses, and what the inference engine […]

Deepgram deepens Amazon SageMaker AI observability with Enhanced Metrics Read More »
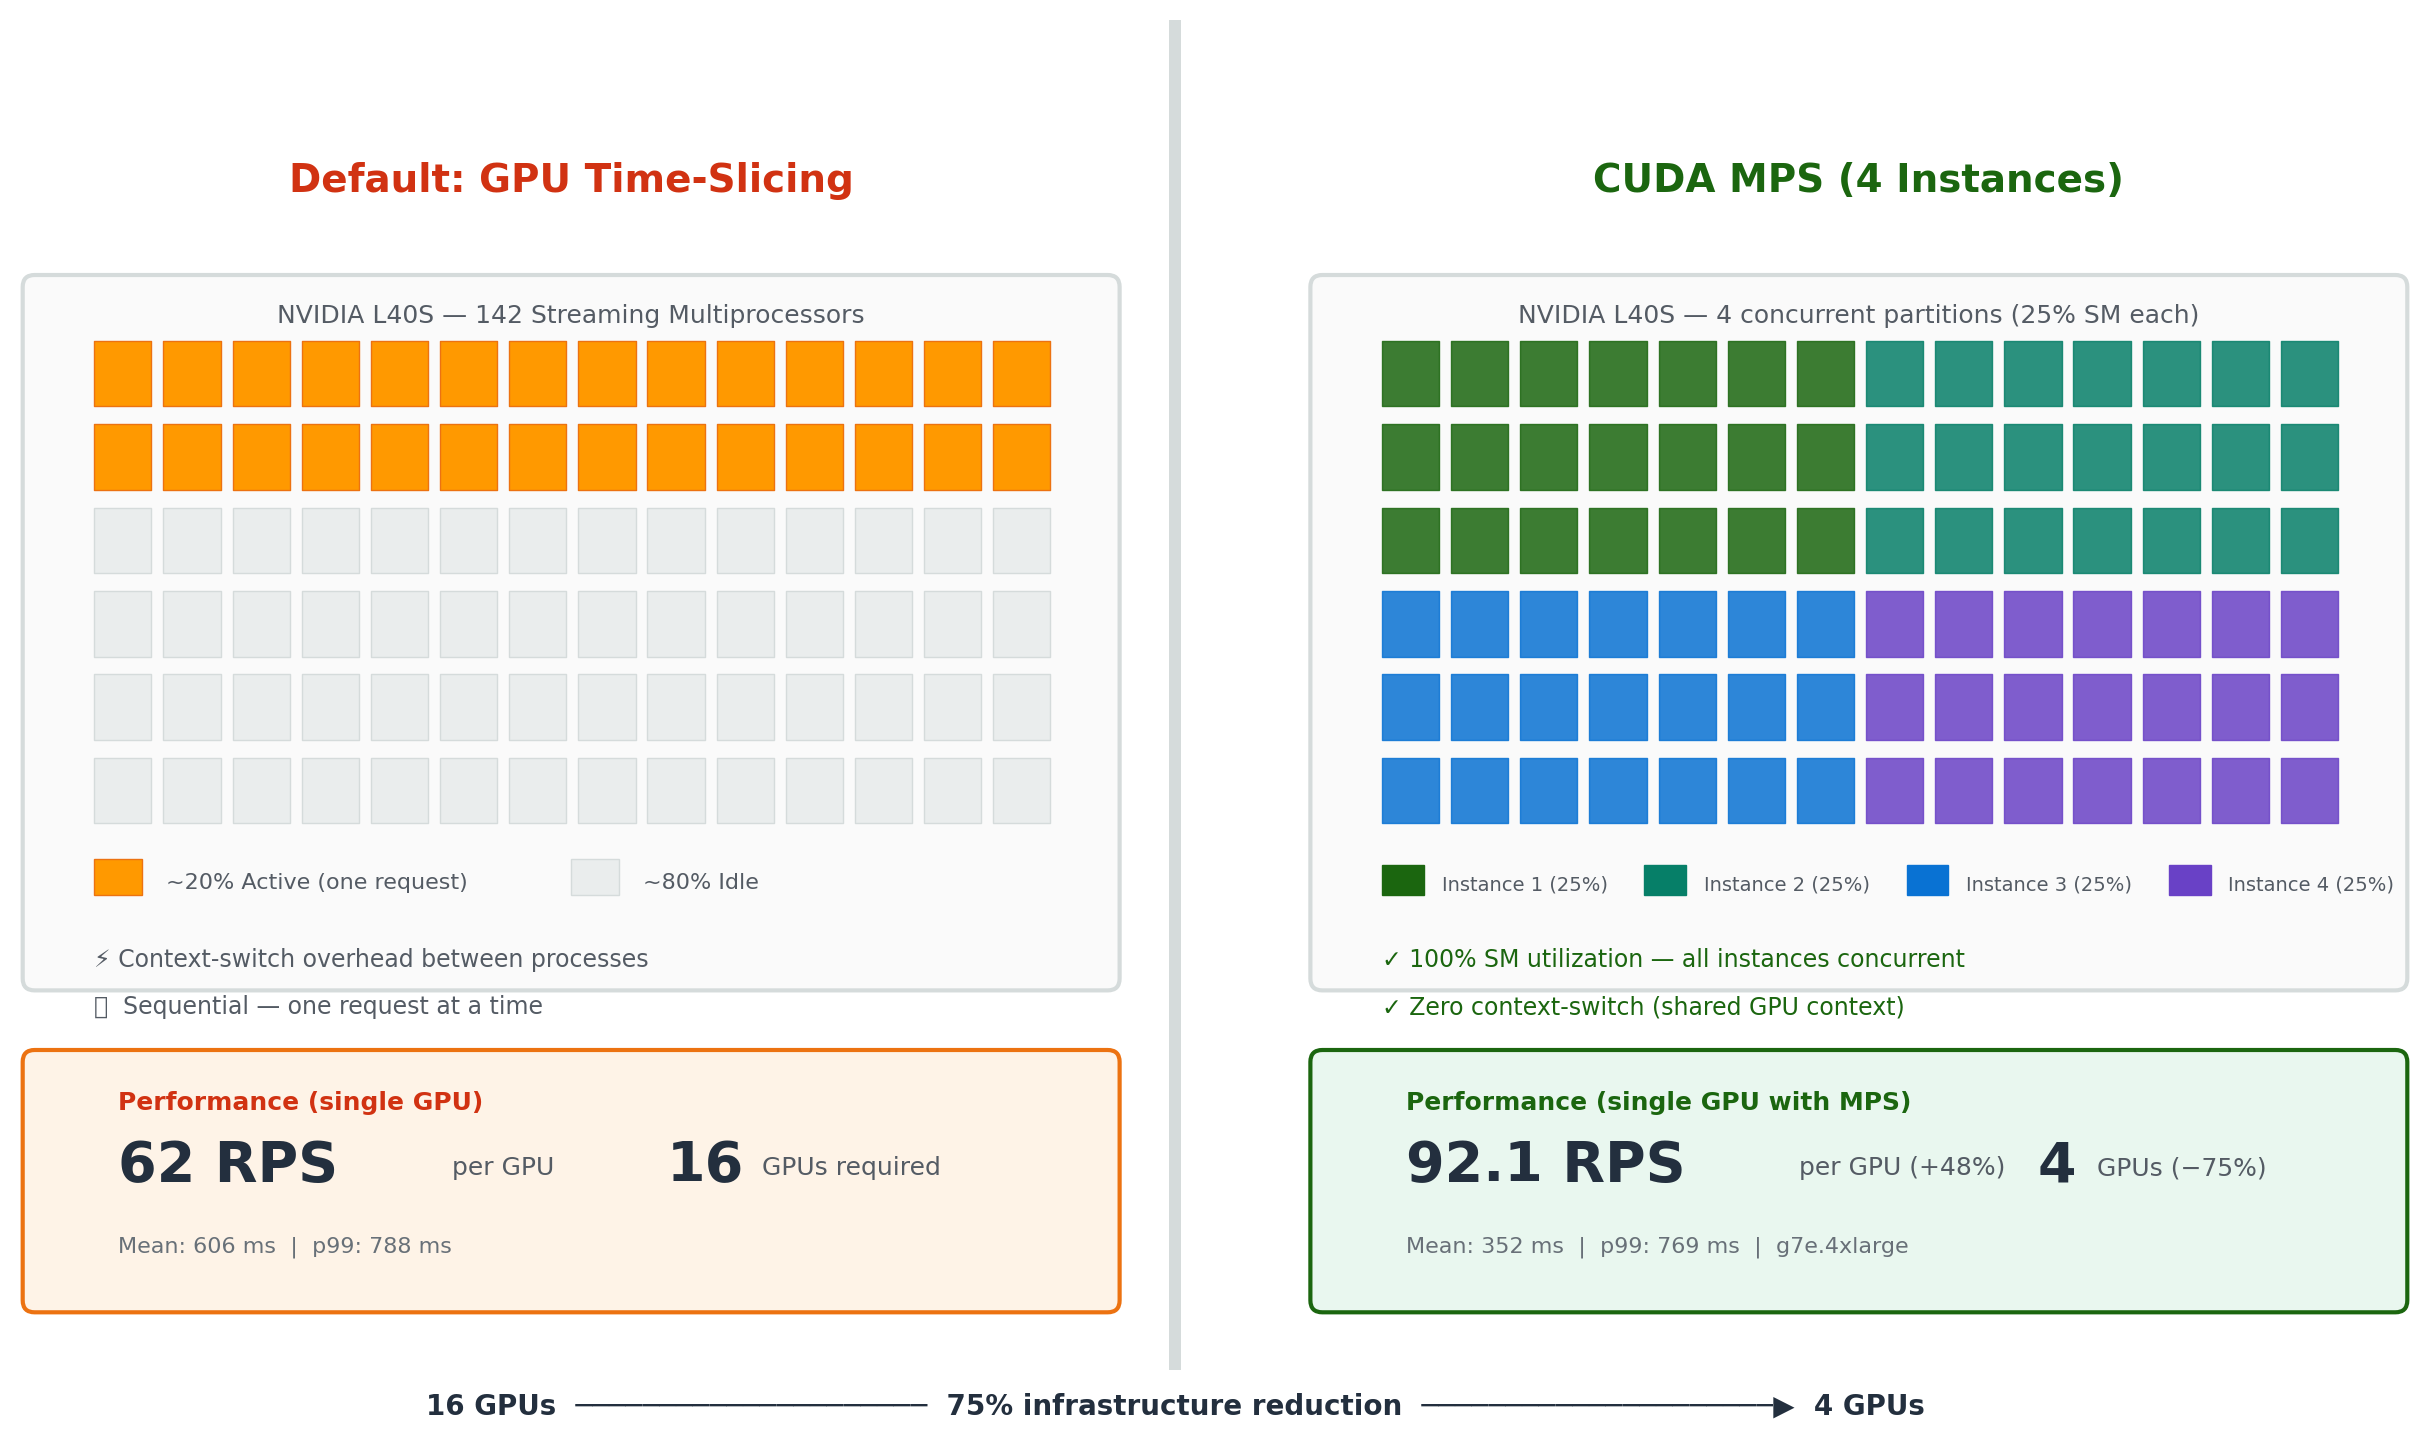
Reduce ASR inference costs by 75% with NVIDIA MPS on Amazon EC2

Reduce ASR inference costs by 75% with NVIDIA MPS on Amazon EC2

This post is a collaboration between AWS, NVIDIA and Heidi. Reducing automatic speech recognition (ASR) inference costs on Amazon Elastic Compute Cloud (Amazon EC2) becomes critical when GPU utilization per request is low but latency requirements are strict. A single ASR inference request typically uses only 15–20 percent of a GPU’s compute capacity, yet the default

Reduce ASR inference costs by 75% with NVIDIA MPS on Amazon EC2 Read More »

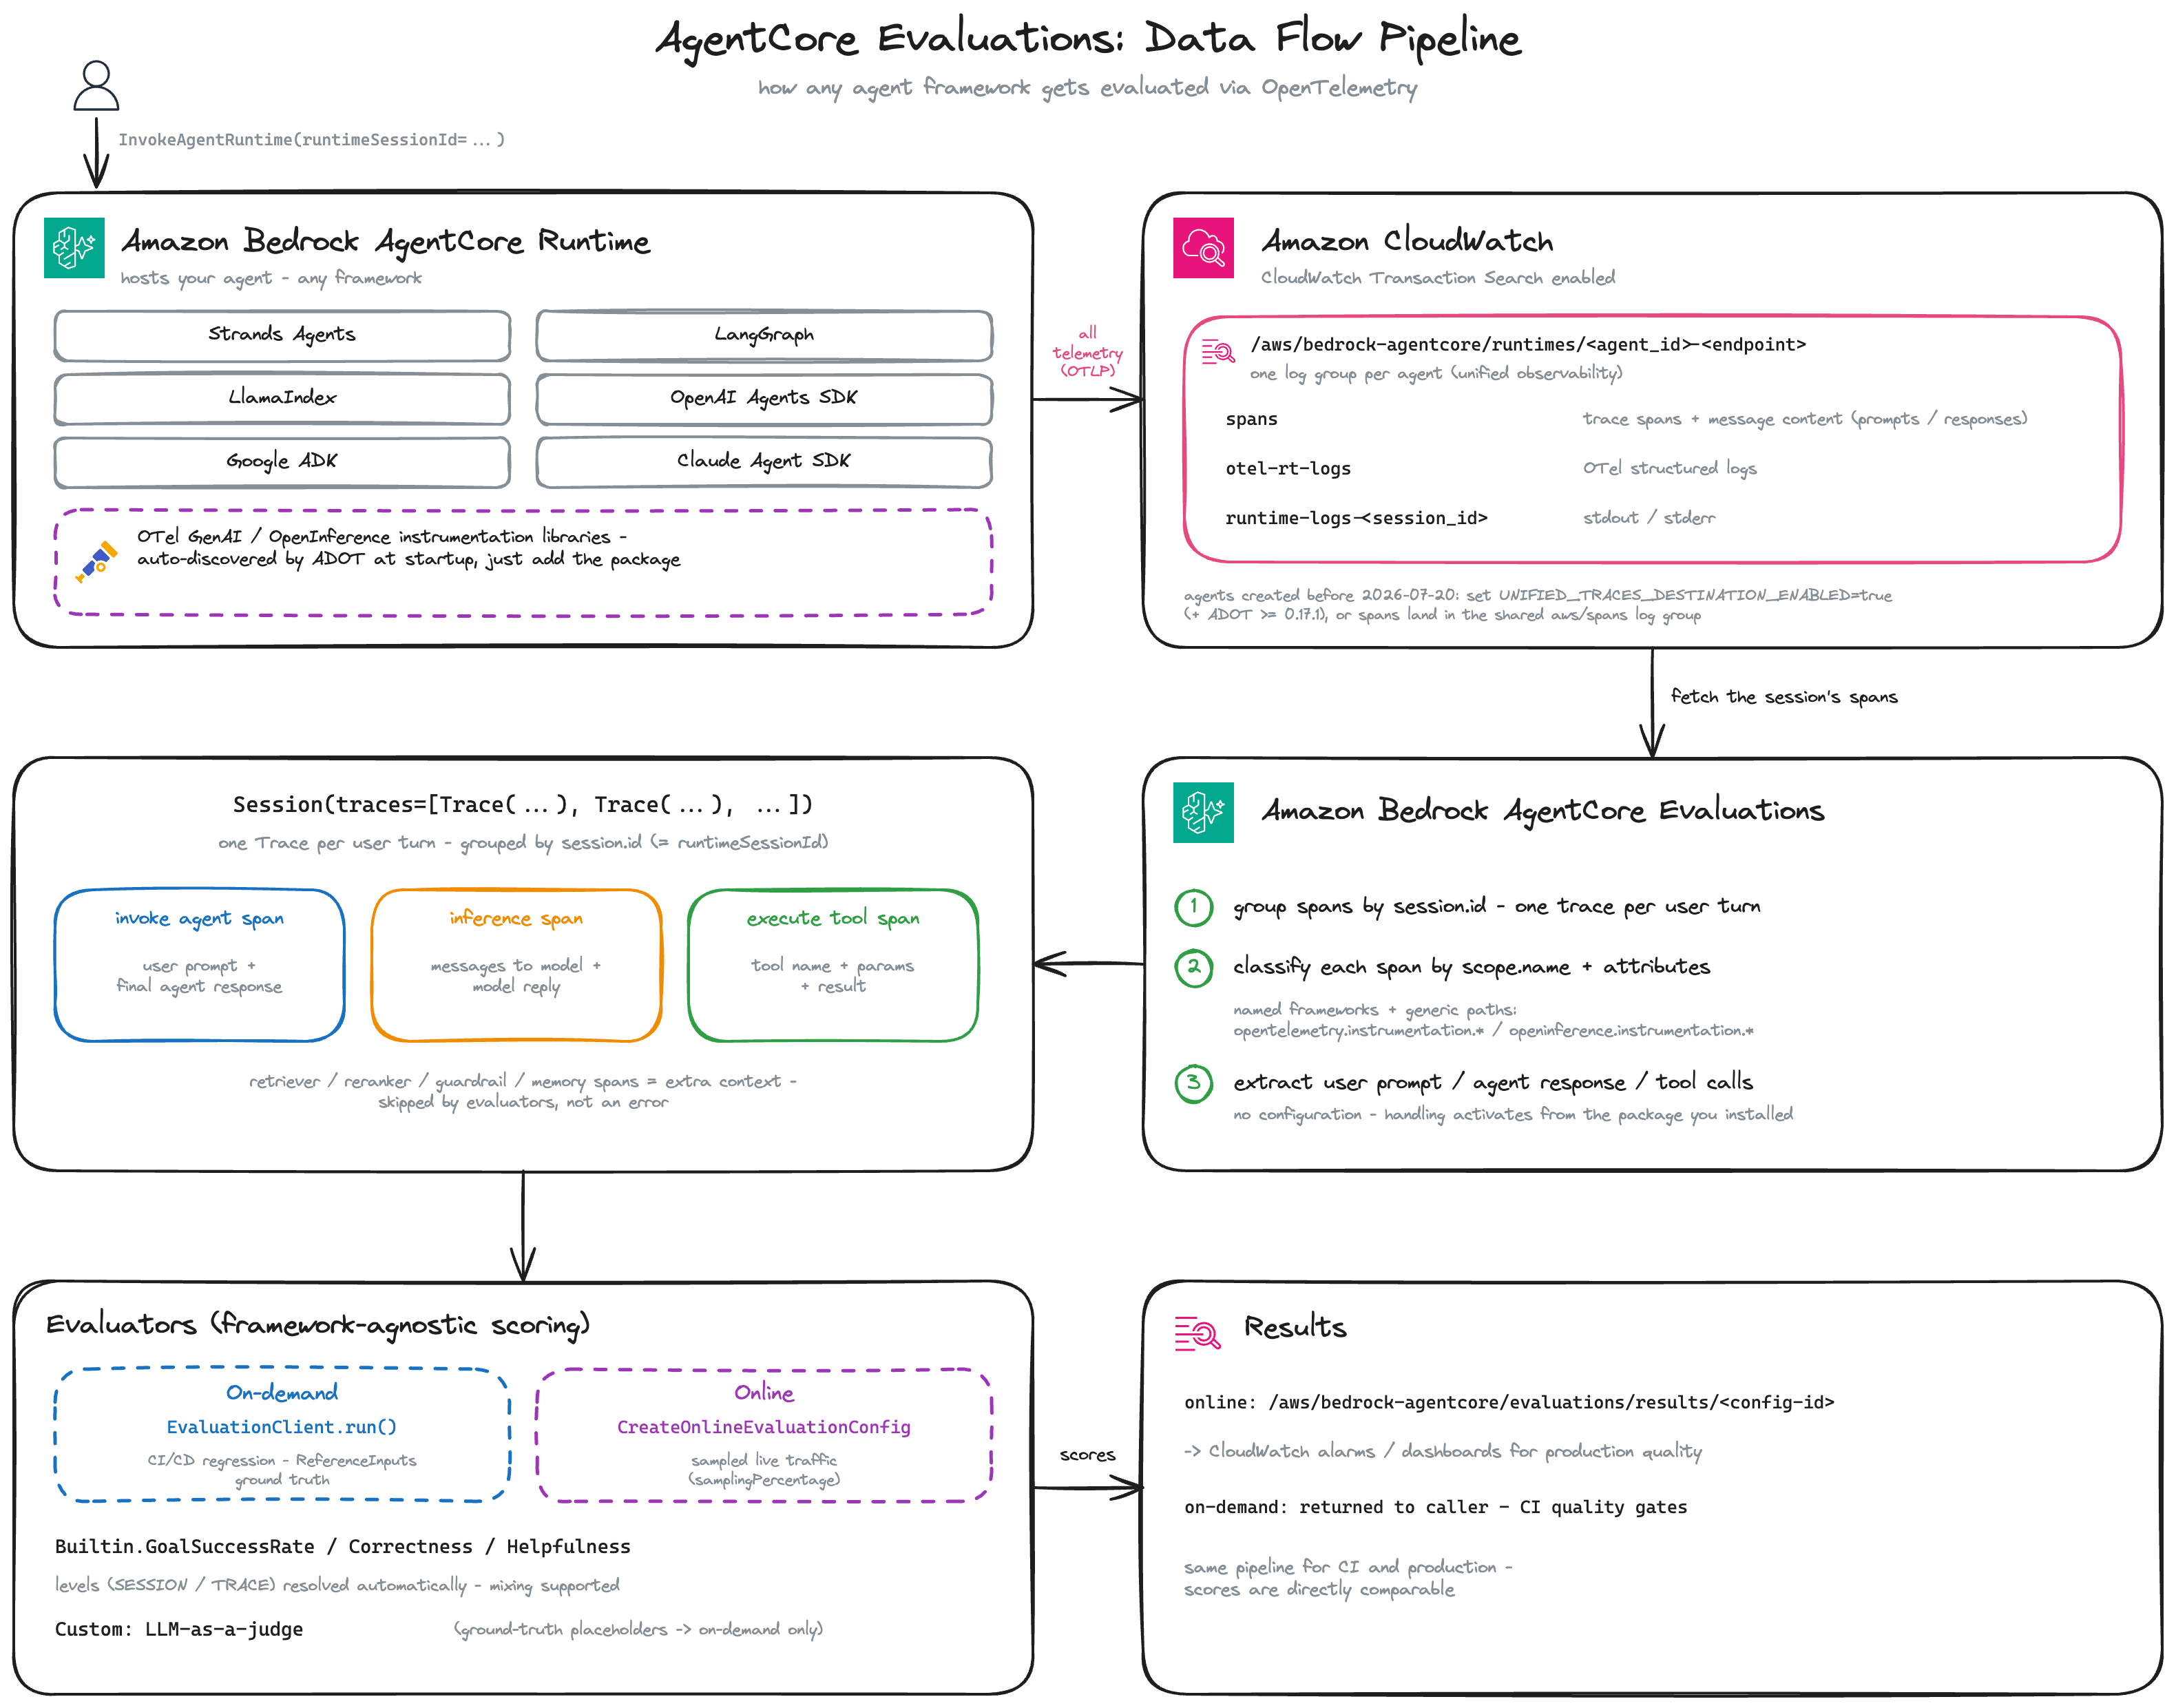
Evaluate any agent framework with Amazon Bedrock AgentCore Evaluations

Evaluate any agent framework with Amazon Bedrock AgentCore Evaluations

AI teams building production agents face a frustrating asymmetry: the diversity of agent frameworks keeps growing, but evaluation tooling has not kept pace. Most evaluation systems assume you built your agent in a specific way: a specific SDK, a specific large language model (LLM) client, a specific tracing pattern. The moment you step outside that

Evaluate any agent framework with Amazon Bedrock AgentCore Evaluations Read More »

How GoDaddy transformed its analytics with Amazon Quick

How GoDaddy transformed its analytics with Amazon Quick

GoDaddy is one of the world’s largest domain registrar and web hosting companies, serving more than 20 million customers and managing approximately 82 million domain names. At that scale, access to timely business data directly affects how quickly the company can act. When GoDaddy’s analytics infrastructure faced challenges under the weight of thousands of dashboards,

How GoDaddy transformed its analytics with Amazon Quick Read More »

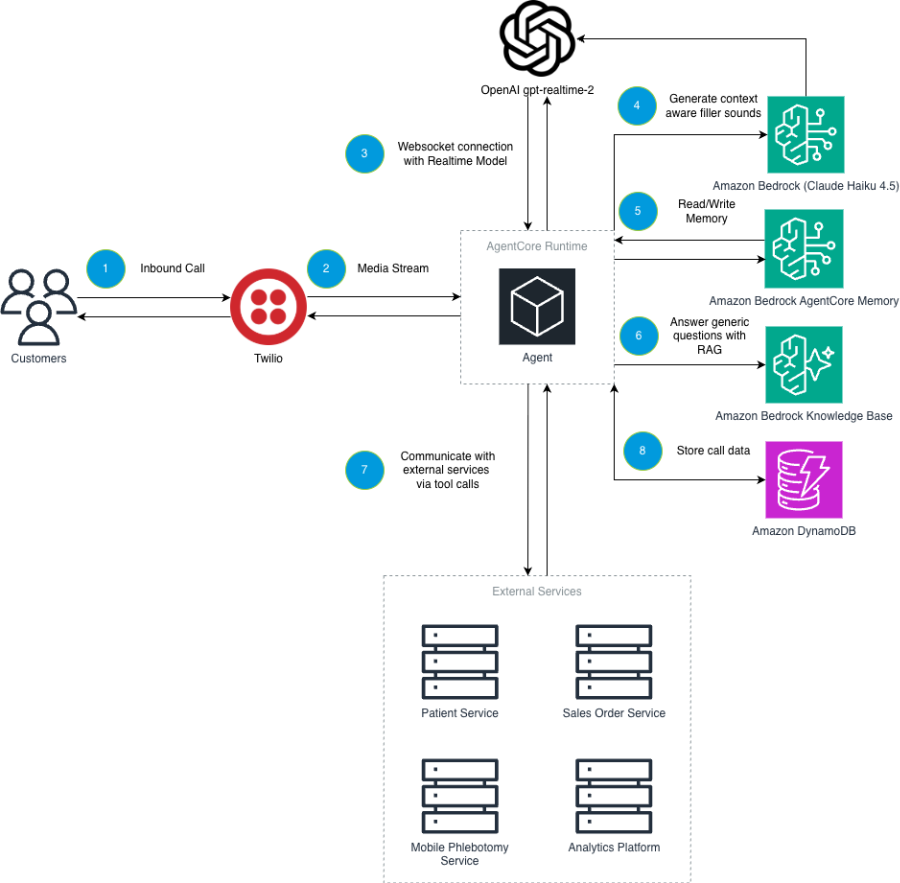
Natera’s intelligent appointment scheduling with Amazon Bedrock AgentCore

Natera’s intelligent appointment scheduling with Amazon Bedrock AgentCore

Booking a phlebotomy appointment shouldn’t be a hassle for oncology patients already managing treatment. Natera’s service, powered by Amazon Bedrock AgentCore, allows a phlebotomist to come to the patient, helping Natera deliver a more convenient experience. Natera, a global diagnostics company specializing in cell-free DNA testing, wanted to transform their patient experience by replacing manual

Natera’s intelligent appointment scheduling with Amazon Bedrock AgentCore Read More »

Bring your own model with Amazon SageMaker AI: Script mode in SDK v3

Bring your own model with Amazon SageMaker AI: Script mode in SDK v3

In 2021, we published Bring your own model with Amazon SageMaker script mode. That post showed how to use script mode on managed framework containers from AWS to write custom training and inference code. Script mode was a leap forward: you didn’t need to build or maintain Docker images to run your own algorithm on

Bring your own model with Amazon SageMaker AI: Script mode in SDK v3 Read More »

Preparing data for supervised fine-tuning Part 2: Advanced data strategies

Preparing data for supervised fine-tuning Part 2: Advanced data strategies

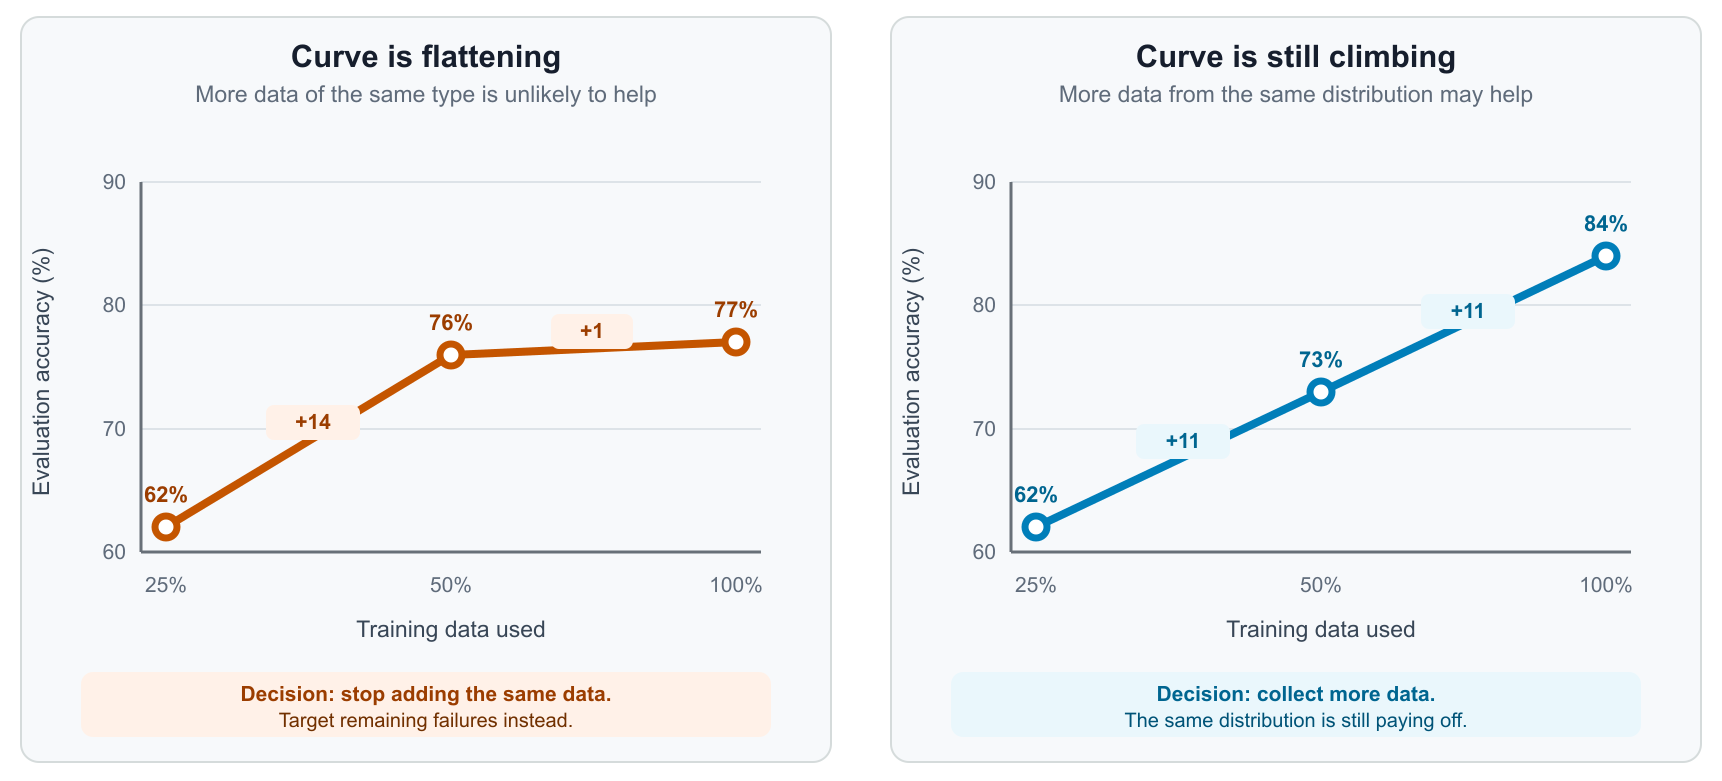
Data preparation for supervised fine-tuning (SFT) doesn’t end when your dataset is clean and correctly formatted. The harder questions come next. How much data do you actually need? Should you collect more, or select a better subset of what you have? How do you generate high-quality examples when human annotation doesn’t scale? And how do

Preparing data for supervised fine-tuning Part 2: Advanced data strategies Read More »

Preparing data for supervised fine-tuning Part 1: Formatting and quality

Preparing data for supervised fine-tuning Part 1: Formatting and quality

Data preparation determines the ceiling of any supervised fine-tuning (SFT) project. You’ve evaluated your foundation model (FM), and out-of-the-box performance isn’t meeting your production requirements. Maybe the model doesn’t follow your output schema reliably, struggles with your domain’s classification taxonomy, or can’t maintain the tone your application demands. The question isn’t whether to customize, it’s

Preparing data for supervised fine-tuning Part 1: Formatting and quality Read More »

Connect Amazon Bedrock AgentCore to cross-account knowledge bases

Connect Amazon Bedrock AgentCore to cross-account knowledge bases

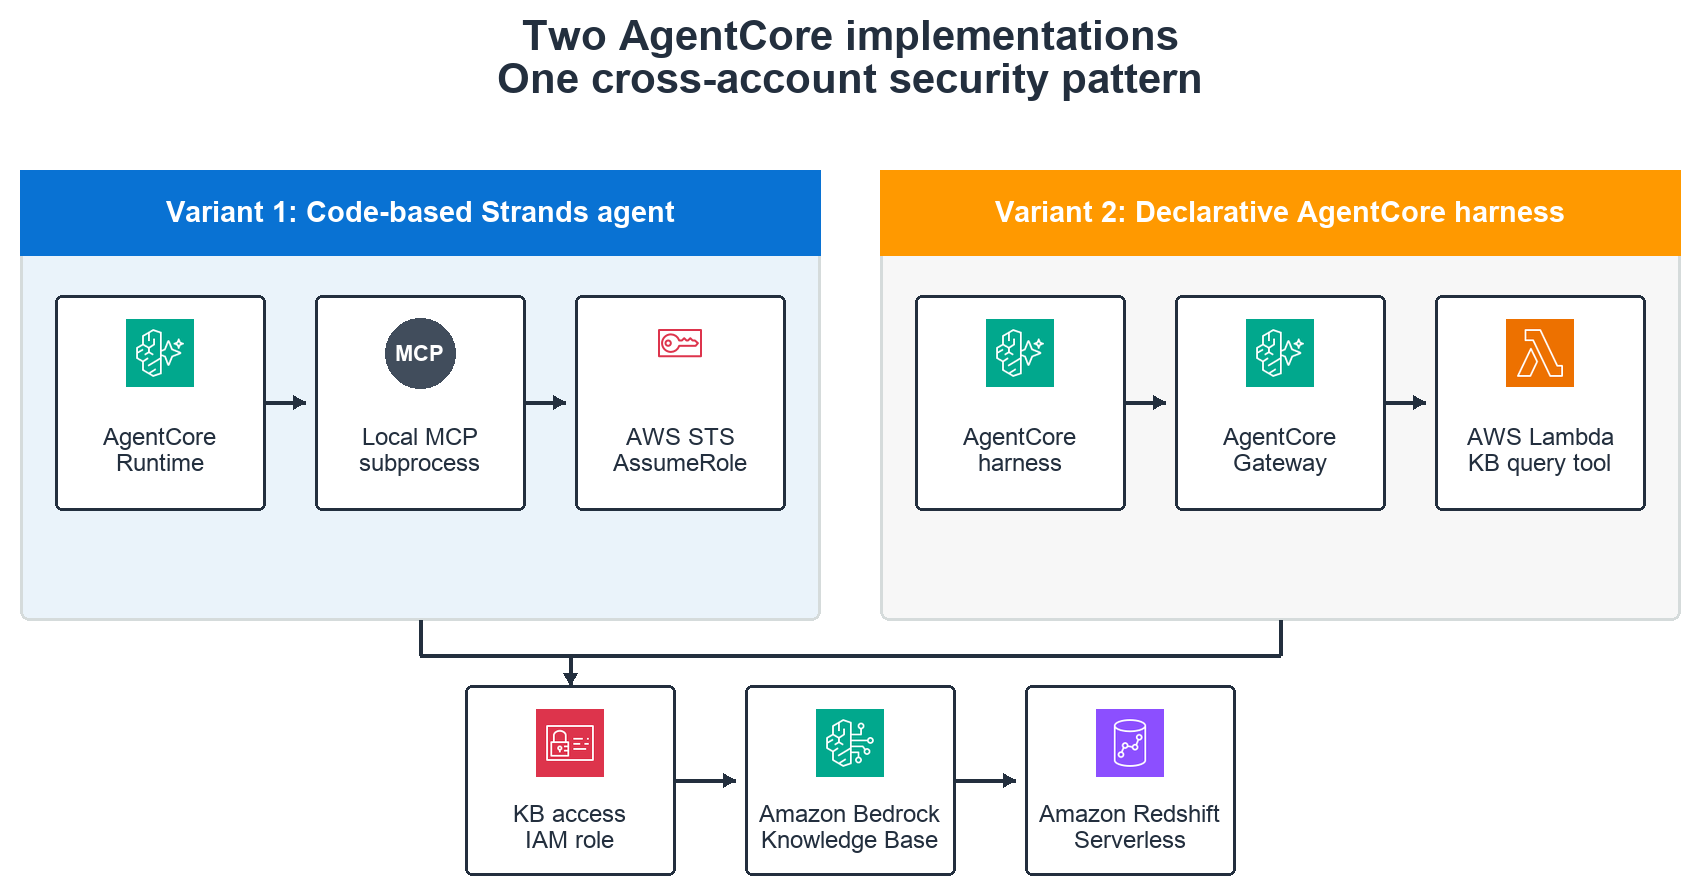
Organizations often deploy agents using Amazon Bedrock AgentCore, a platform to build, connect, and optimize agents at scale, with any framework or model. These agents may access governed knowledge bases hosted in separate AWS accounts. This cross-account separation helps maintain clear workload boundaries but can introduce integration challenges. This post explains how AgentCore agents in

Connect Amazon Bedrock AgentCore to cross-account knowledge bases Read More »

Scroll to Top