Large-scale distributed training jobs run for hours or days across dozens of nodes. At that scale and duration, interruptions are statistically inevitable: network partitions, memory errors, software exceptions, or infrastructure events will eventually disrupt at least one worker. A single GPU fault triggers a cascade: NVIDIA Collective Communication Library (NCCL) timeouts propagate to healthy workers, pods crash and restart out of sync, and your cluster burns expensive GPU hours while making zero training progress. Synchronous checkpointing adds a second source of idle time: every save blocks all ranks on I/O, which on the cluster sizes in this post consumed up to 40% of total wall time.
In this post, we show how to integrate NVIDIA Resiliency Extension (NVRx) into PyTorch Fully Sharded Data Parallel (FSDP) training on Amazon Elastic Kubernetes Service (Amazon EKS) to solve both problems. You walk through async checkpointing that overlaps I/O with training, in-process restart that recovers from faults in seconds without touching the container lifecycle, and in-job restart using ft_launcher for automatic worker respawn on hard crashes. We include benchmark results on H100 GPUs at 2-node to 8-node scale, with all code available to reproduce.
Solution overview
The solution combines NVRx fault tolerance primitives with an EKS-based training environment designed for high-performance multi-node GPU workloads. NVRx handles the application-level resilience (async checkpointing, in-process restart, and in-job restart), while the EKS cluster provides the infrastructure foundation: GPU scheduling, high-bandwidth networking, and shared storage for checkpoint persistence.
NVRx
The NVIDIA Resiliency Extension (NVRx) is a pip-installable Python layer (pip install nvidia-resiliency-ext) that adds fault-tolerance primitives to PyTorch: no custom kernels, no PyTorch fork, no recompile. The primitives drop into an existing FSDP script as ordinary imports. The model and training code stay untouched. Each is independently adoptable. We exercised three features: async checkpointing, in-process restart, and ft_launcher (in-job restart).
Async checkpointing, exposed through TorchAsyncCheckpoint, replaces torch.save with an async_save() call that hands the state dict to a background process and returns immediately. A matching finalize_async_save() before the next save commits the prior write. Paired with FSDP LOCAL_STATE_DICT, each rank writes its own shard directly, with no all-gather and no rank-0 bottleneck.
In-process restart, exposed through inprocess.Wrapper, wraps the train function so a transient fault (an unhandled exception or an NCCL hang) does not kill the Python process. NVRx aborts the active process group, runs health checks per rank (GPU, NVLink, NIC), re-rendezvouses survivors, and re-enters the wrapped function from the latest checkpoint. The interpreter, CUDA allocator, and outer-scope objects survive. This catches the soft-fault class.
The ft_launcher binary, the NVRx in-job restart launcher, handles cases in-process cannot catch: SIGKILL, out-of-memory (OOM) kill, and OS-level hangs. Each rank runs a RankMonitorClient. The launcher checks heartbeats against explicit CLI-set timeouts, and on stall or death it kills survivors, reclaims GPU memory, and respawns fresh workers in the same job. Recovered workers reload from the latest checkpoint. Each recovery layer covers a distinct fault class: in-process for soft faults, ft_launcher for hard faults, and the cluster orchestrator for node loss. The layers are independent. Pick the one whose scope matches your failure modes.
Amazon EKS cluster
Amazon EKS is a managed Kubernetes service that handles the control plane, upgrades, and API server availability. We run self-managed node groups of p5.48xlarge instances, each with 8 NVIDIA H100 80 GB GPUs and 32 Elastic Fabric Adapter (EFA) network interfaces. Training pods run as Kubernetes Jobs with headless Services for peer discovery, so workers find each other through DNS rather than hardcoded IPs, and pod replacements can rejoin without reconfiguring the job.
Each node exposes its GPUs and EFA adapters as extended resources through the NVIDIA device plugin and EFA device plugin. The Kubernetes scheduler places training pods on GPU nodes using node affinity and tolerations, facilitating the full 8-GPU allocation per node.
For checkpoint storage, we use Amazon FSx for Lustre (SCRATCH_2, 1.2 TB) mounted into every training pod through the FSx CSI driver. FSx provides the shared filesystem that both async and synchronous checkpointing write to, and critically, it is where recovering workers read their checkpoint state after a fault. Placing FSx in the same Availability Zone as the GPU nodes minimizes read latency during recovery, which matters because checkpoint loading (not the restart mechanism) dominates recovery time at scale.
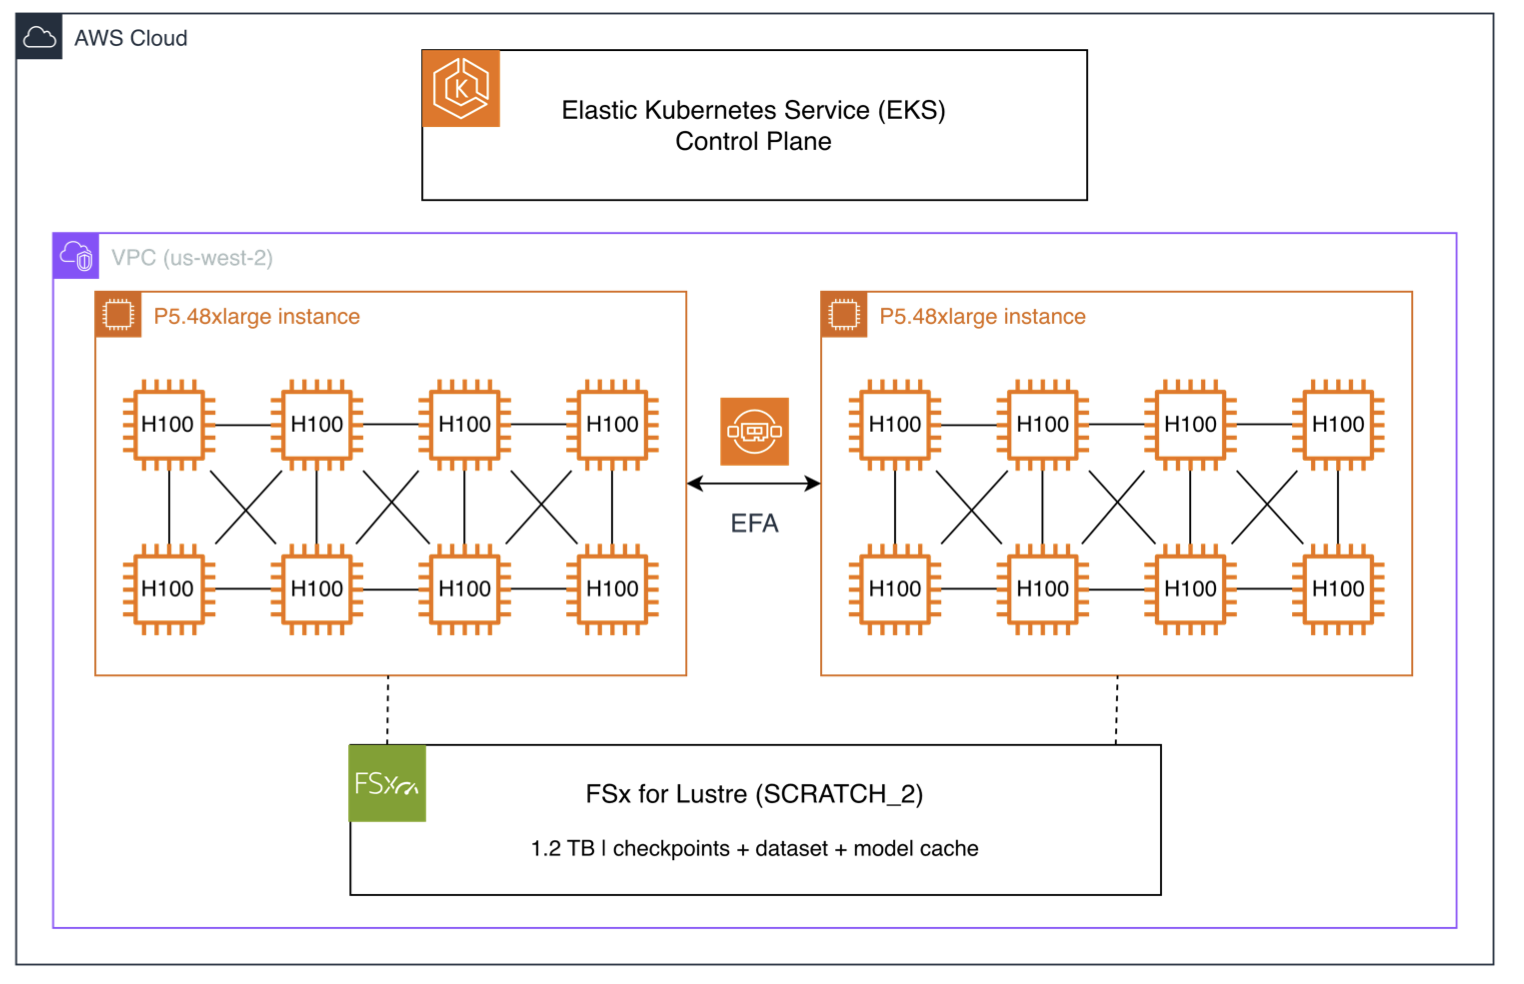
Figure 1: Architecture diagram showing the EKS cluster with 2-8 p5 nodes, EFA interconnect, FSx for Lustre, and NVRx components within training pods
The key AWS services involved:
- Amazon EKS — Kubernetes control plane, pod scheduling, Job lifecycle management.
- Amazon Elastic Compute Cloud (Amazon EC2) p5.48xlarge — 8x H100 80 GB GPUs, 32x EFA adapters per node.
- Elastic Fabric Adapter (EFA) — 3,200 Gbps network bandwidth for NCCL all-reduce operations.
- Amazon FSx for Lustre — Shared POSIX filesystem for distributed checkpoint I/O.
- Amazon Elastic Container Registry (Amazon ECR) — Container registry for the training image (PyTorch + NVRx + model code)
Prerequisites
Before deploying this solution, make sure you have the following infrastructure and tooling in place:
- AWS account with service quota for p5.48xlarge (or p4de.24xlarge) instances.
- Amazon EKS cluster (v1.28+) with EFA-enabled self-managed GPU node groups and the NVIDIA device plugin installed.
- Amazon FSx for Lustre filesystem (SCRATCH_2) in the same Availability Zone as the GPU nodes.
- Container image with PyTorch 2.9+, NVRx 0.4.1 to reproduce the benchmark results shown in this post. Use v0.6.0 with an updated launcher configuration for a current deployment and your training code, pushed to Amazon ECR.
- kubectl configured for your cluster.
- HuggingFace account with access to
meta-llama/Llama-3.1-8B(or your model of choice) - Training dataset pre-downloaded to shared storage (we use 100K samples from the C4 dataset. You can use a dataset of your choice)
For EKS cluster creation with GPU nodes and EFA networking, see the infrastructure guides in awsome-distributed-ai/1.architectures. For the complete NVRx-specific setup including Terraform modules, container build, and dataset preparation, see the NVRx test case README.
Solution walkthrough
NVRx exposes two orthogonal changes to a standard PyTorch FSDP script: async checkpointing (a write-path optimization) and recovery, which comes in two independent layers: in-process restart for soft faults and ft_launcher in-job restart for hard faults. The test case ships a separate script per capability, so you adopt only what you need.
We start from a baseline FSDP script with synchronous checkpointing, then introduce each NVRx capability independently (async checkpointing, in-process restart, and the ft_launcher in-job restart) and close with a short note on how the recovery layers compose.
Baseline FSDP training script
Start with a minimal FSDP loop launched by torchrun using a synchronous distributed checkpoint save (PyTorch’s torch.distributed.checkpoint.save under the hood). The save blocks every rank until per-rank shards land on shared storage, and a worker crash kills the entire training job, requiring a full restart from the last checkpoint.
Async checkpointing: decouple checkpoint I/O from training

Figure 2: NVRx async checkpoint pipeline
Replace the synchronous save with the NVRx TorchAsyncCheckpoint: instantiate it once with persistent_queue=True, call async_save(state_dict, path) in place of torch.save, and call finalize_async_save(blocking=True) once as a blocking finalization at job exit, as shown in figure 2. A background process owns the actual write. The main thread continues to the next forward/backward step. Each rank writes its own shard through FSDP LOCAL_STATE_DICT, with no all-gather and no rank-0 bottleneck.
In-process restart
Wrap the train function with inprocess.Wrapper. The wrapper owns the restart loop: an exception in the wrapped function (or a hang the watchdog detects) triggers a re-entry instead of crashing the process. The constructor wires four concerns: timeouts (soft_timeout, hard_timeout, barrier_timeout, completion_timeout), health checks (CudaHealthCheck + FaultCounter), a RetryController that caps the total number of restarts and sets a minimum surviving world size, and rank assignment (ActivateAllRanks + ShiftRanks) that pulls survivors left to keep the world contiguous.

Figure 3: NVRx in-process restart architecture
Behind the scenes (as shown in figure 3): a ProgressWatchdog (progress_watchdog.py:49) uses Py_AddPendingCall to write timestamps between bytecode instructions, so a hang inside NCCL (a C extension) is still detectable. A MonitorThread (monitor_thread.py:124) polls the inprocess TCPStore for an interrupted flag and raises RankShouldRestart into the main thread on detection. AbortTorchDistributed (abort.py:62) then collects Flight Recorder traces, aborts NCCL backends, and destroys the process group. Health checks pick survivors. The Python process stays alive, and only the distributed process group is rebuilt.
In-job restart (ft_launcher)
Switch the launcher from torchrun to ft_launcher. It understands the same rendezvous flags and adds a few of its own to control restart behavior:
Inside the train script, instantiate RankMonitorClient once after distributed init and send a heartbeat each step:
Set --ft-rank-heartbeat-timeout above the longest legitimate interval between application heartbeats. The example uses 900 seconds. Setting --ft-initial-rank-heartbeat-timeout=1200 (20 minutes) accommodates first-time model loading. See kubernetes/training-job-ft-launcher.yaml.

Figure 4: NVRx in-job restart (ft_launcher) architecture
Behind the scenes (as shown in figure 4): a RankMonitorServer per rank tracks heartbeat intervals against the timeouts above. On timeout, the launcher SIGTERMs survivors (SIGKILL for stragglers), reclaims GPU memory, re-rendezvouses, and spawns fresh workers. Workers reload from the latest checkpoint on startup. Checkpoint frequency caps the amount of lost work.
How the layers cover distinct fault classes
The two recovery layers are scoped to different failure modes: in-process catches what fits inside one Python process (transient exceptions, watchdog-visible NCCL hangs), ft_launcher catches what kills the process or hangs at the OS level (SIGKILL, OOM, sub-Python deadlocks), and the cluster scheduler catches node loss. Pick the layer whose blast radius matches your failure modes. Async checkpointing is orthogonal: it pairs with a recovery layer (or none) and caps the lost-work blast radius.
Deploy and run experiments
We deploy training jobs using a thin wrapper script around kubectl that handles manifest templating, job cleanup, and environment variable substitution. Environment variables define the instance type, GPU count, number of EFA devices, and other hardware-specific parameters, so the same training code and manifests run on different GPU types (p5, p4de) by changing a single configuration file. To compare recovery mechanisms under identical conditions, we use deterministic fault injection, pre-generating exactly N faults at fixed training steps and ranks using a seeded RNG:
The same seed produces the same fault schedule across experiments, enabling direct comparison between baseline K8s restart, ft_launcher, and NVRx in-process restart. We run each mechanism against the same 5-fault pattern, then run async vs sync checkpointing separately without fault injection to isolate checkpoint overhead.
Results
This section presents benchmarking results for two key capabilities: async checkpointing and fault recovery.
Async checkpointing
We benchmarked async (NVRx) vs synchronous (torch.save) checkpointing on LLaMA-3.1-8B FSDP training across two dimensions: scaling from 2 to 8 nodes (16-64 H100 GPUs) with a fixed checkpoint interval of every 1000 steps, and sweeping checkpoint frequency (every 100 to 1000 steps) at 8-node scale.

Figure 5: Sync vs async checkpointing
Async checkpointing maintains 99%+ training efficiency at every scale (99.2% at 2 nodes, 99.8% at 8 nodes), while synchronous checkpointing stays flat at 57-61%, losing ~40% of wall time to blocking I/O regardless of node count. The gap persists because checkpoint overhead is storage-bound: FSx Lustre write time (~275s) is constant whether you have 16 or 64 GPUs. Async hides this latency entirely by overlapping I/O with the next training segment.
When we sweep checkpoint frequency at 8-node scale, the async advantage becomes more pronounced:

Figure 6: Checkpointing frequency impact
At every-1000-steps, async achieves 99.8% efficiency vs 60.3% sync. At every-100-steps, sync plummets to 14.7% while async degrades gracefully to 29.6%, still 2x more efficient. The crossover point is where the training gap between checkpoints (~280s at 100 steps) approaches the FSx I/O time (~275s). Above that threshold, async fully overlaps. Below it, partial overlap still outperforms blocking writes.
What this means: Teams training at scale often checkpoint infrequently to avoid the blocking penalty, accepting hours of lost progress when faults occur. Async checkpointing removes that tradeoff: you can checkpoint aggressively (every few minutes) with near-zero overhead, minimizing rollback distance without sacrificing GPU utilization.
Fault recovery
We ran fault recovery experiments on 2 p5.48xlarge nodes (16 H100 GPUs total) training LLaMA-3.1-8B with FSDP, checkpointing every 500 steps over a 2000-step run. We injected 5 deterministic faults into each training run (same seed, same fault schedule) and compared three recovery mechanisms:

Figure 7: Comparing fault recovery methods: in-process restart vs in-job restart vs Kubernetes restart
NVRx in-process restart achieves 31% training goodput with 87% infrastructure goodput, recovering in ~10 seconds with zero container restarts. ft_launcher achieves 25.5% training goodput (85.9% infra goodput) with 17s recovery per fault. Baseline Kubernetes restart is catastrophic: 11.5% training goodput, 35.8% infra goodput, and 270s recovery per fault. The baseline failure mode is a cascade: one rank crashes, the surviving rank hits an NCCL timeout (60s), then both pods restart out of sync, triggering CrashLoopBackOff and additional timeout cycles before training can resume.
What this means: At large-scale training (hundreds to thousands of GPUs), hardware faults occur every few hours. With baseline Kubernetes recovery consuming 4+ minutes per fault, a cluster experiencing 3-4 faults per hour would spend more time recovering than training. NVRx reduces that recovery window to seconds, keeping GPU utilization high even as fault frequency increases with scale.
Clean up
To avoid ongoing charges, remove the resources you created. Order matters: Kubernetes objects that mount FSx must go before the filesystem itself, or deletion blocks on volume finalizers.
- Delete training jobs.
- Release the volume claim.
The PersistentVolume uses persistentVolumeReclaimPolicy: Retain, so this detaches the filesystem without deleting it, and FSx keeps billing until you remove it in step 4. Copy any results you want to keep off /checkpoints first. Deleting a SCRATCH_2 filesystem is permanent and takes no final backup.
- Scale GPU node groups to zero.
On-demand instances stop billing once terminated. With EC2 Capacity Blocks the reservation fee is charged up front, so releasing early recovers nothing, but scale down at least 30 minutes before the block ends, since EC2 begins terminating Capacity Block instances ahead of the end time.
- Delete the filesystem, image repository, and cluster.
Then remove the EKS cluster and GPU node groups using whichever tool provisioned them (terraform destroy, eksctl delete cluster, or CloudFormation), so infrastructure state stays consistent.
For job-level teardown in context, see Stop Training (https://github.com/awslabs/awsome-distributed-ai/tree/main/examples/training/nvrx/kubernetes#8-stop-training) in the test case README.
Conclusion
In this post, we demonstrated how combining NVIDIA Resiliency Extension (NVRx) with Amazon EKS unlocks more efficient distributed PyTorch training by alleviating two common bottlenecks: checkpoint blocking and fault recovery.
In the reported runs, async checkpointing reduced blocking I/O and was measured at 99%+ training efficiency from 16 to 64 H100 GPUs. For fault recovery, NVRx in-process restart can recover in ~10 seconds with zero container restarts, while ft_launcher handles hard faults (SIGKILL, hangs) that crash the process entirely. Both represent a step change from baseline Kubernetes recovery, where NCCL timeout cascades and CrashLoopBackOff storms consume 4+ minutes per fault.
The combination of these features means teams can checkpoint aggressively and recover quickly, maximizing both data protection and GPU utilization.
Next steps
- Try the full reproducible example in the awsome-distributed-ai repository.
- Explore combining async checkpointing with fault recovery for maximum training efficiency, reducing both rollback distance and recovery time simultaneously.
References
- NVIDIA Resiliency Extension.
- Awsome-distributed-ai showcasing NVRx integration with EKS
- GTC talk: Build Fault-Tolerant Distributed AI Training at Scale
- Amazon Elastic Kubernetes Service (Amazon EKS)
- Amazon FSx for Lustre
- Amazon Elastic Container Registry (Amazon ECR)
- Elastic Fabric Adapter (EFA)
- Distributed training with Amazon EKS and Torch Distributed Elastic
About the authors